No Latency
AI responds the instant the user acts, with no server round-trip. Real-time camera, voice, and live features feel snappy, and snappy keeps people coming back.
curl -fsSL https://raw.githubusercontent.com/zetic-ai/melange-cli/main/script/install.sh | shOr paste this command into your coding agent.
Melange automates model optimization, benchmarks on real devices, and generates SDK code to bring AI into your mobile app.
Built by engineers from
Why On-Device AI
Problem
Fragmented hardware, inconsistent performance, months of manual NPU tuning per chip. That's what building on-device AI looks like today. This is what Zetic solves.
Solution
Cutting 6+ months of engineering into 1 hour
In practice
Without Melange, we wouldn't have been able to demonstrate our model's feasibility in real-world situations running on local hardware.
 William WangSpectra team · Stanford
How it works
Go from a raw AI Model to Shippable Mobile App Integration in 1 hour
Upload your model, use a Hugging Face link, or choose from the model library.
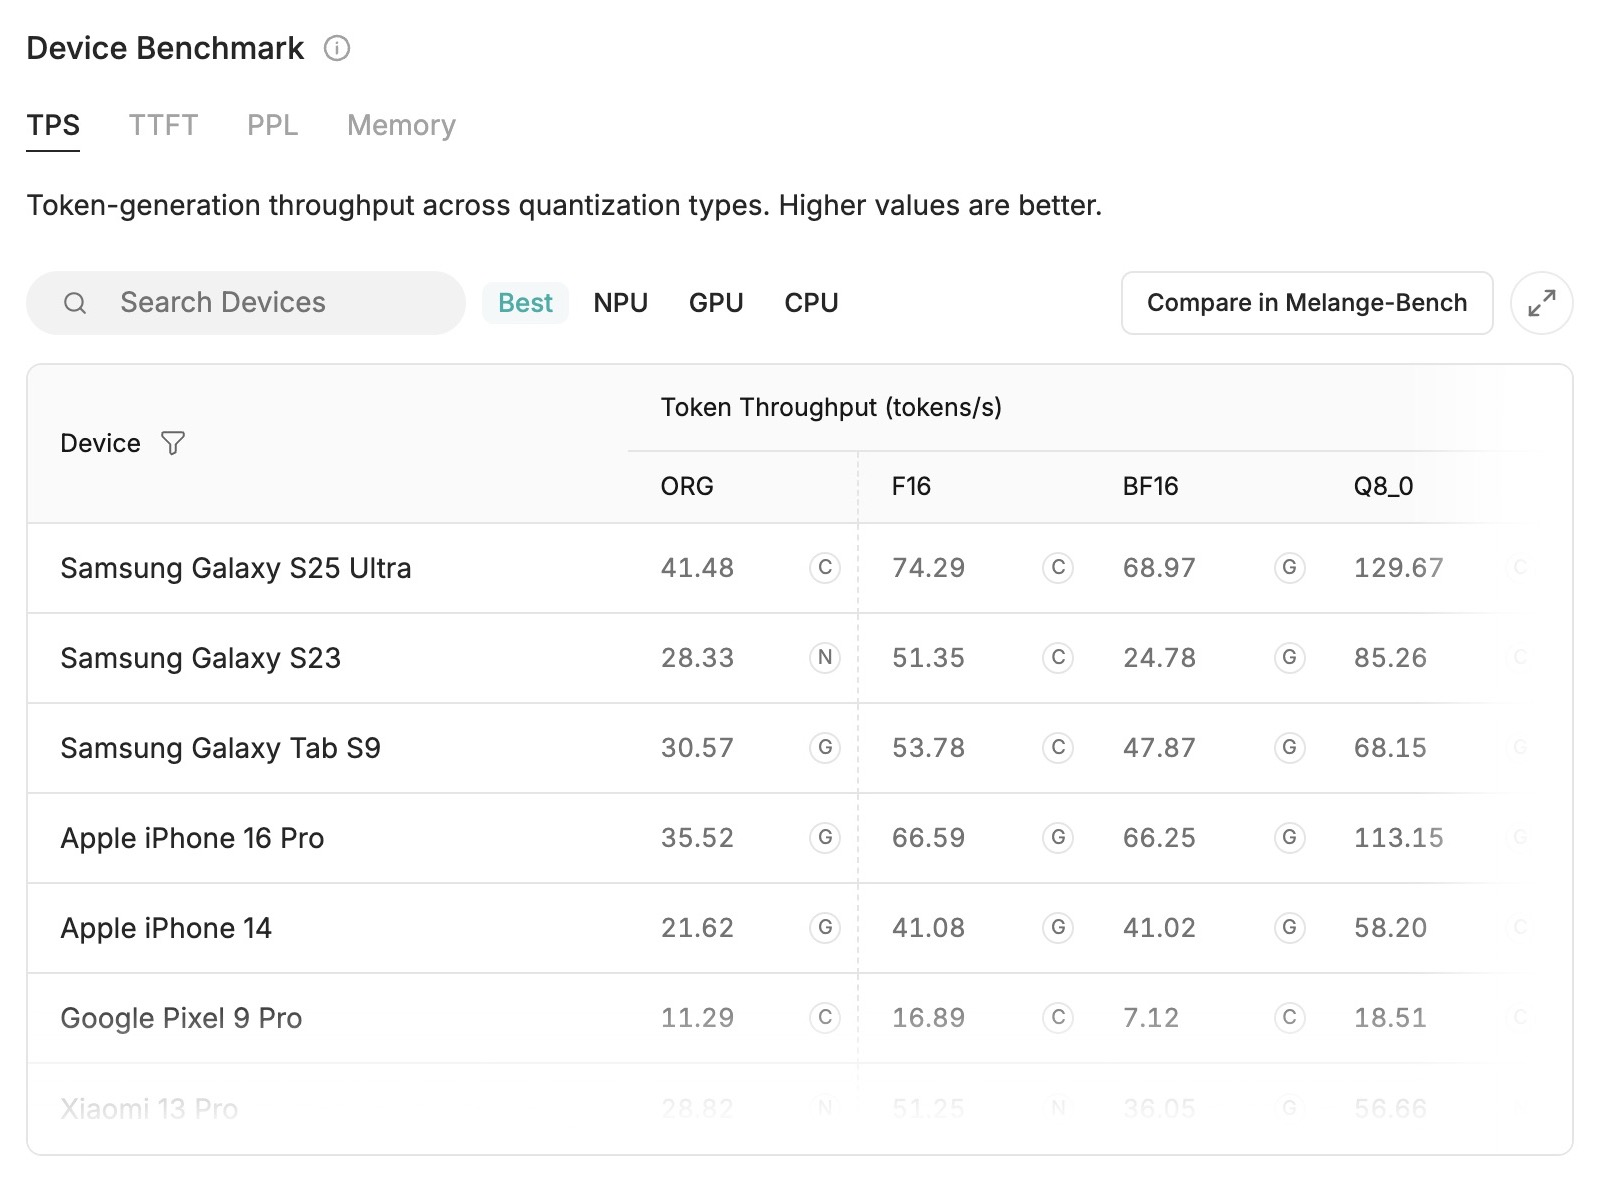
Compare measured performance on real devices and choose your deployment settings.
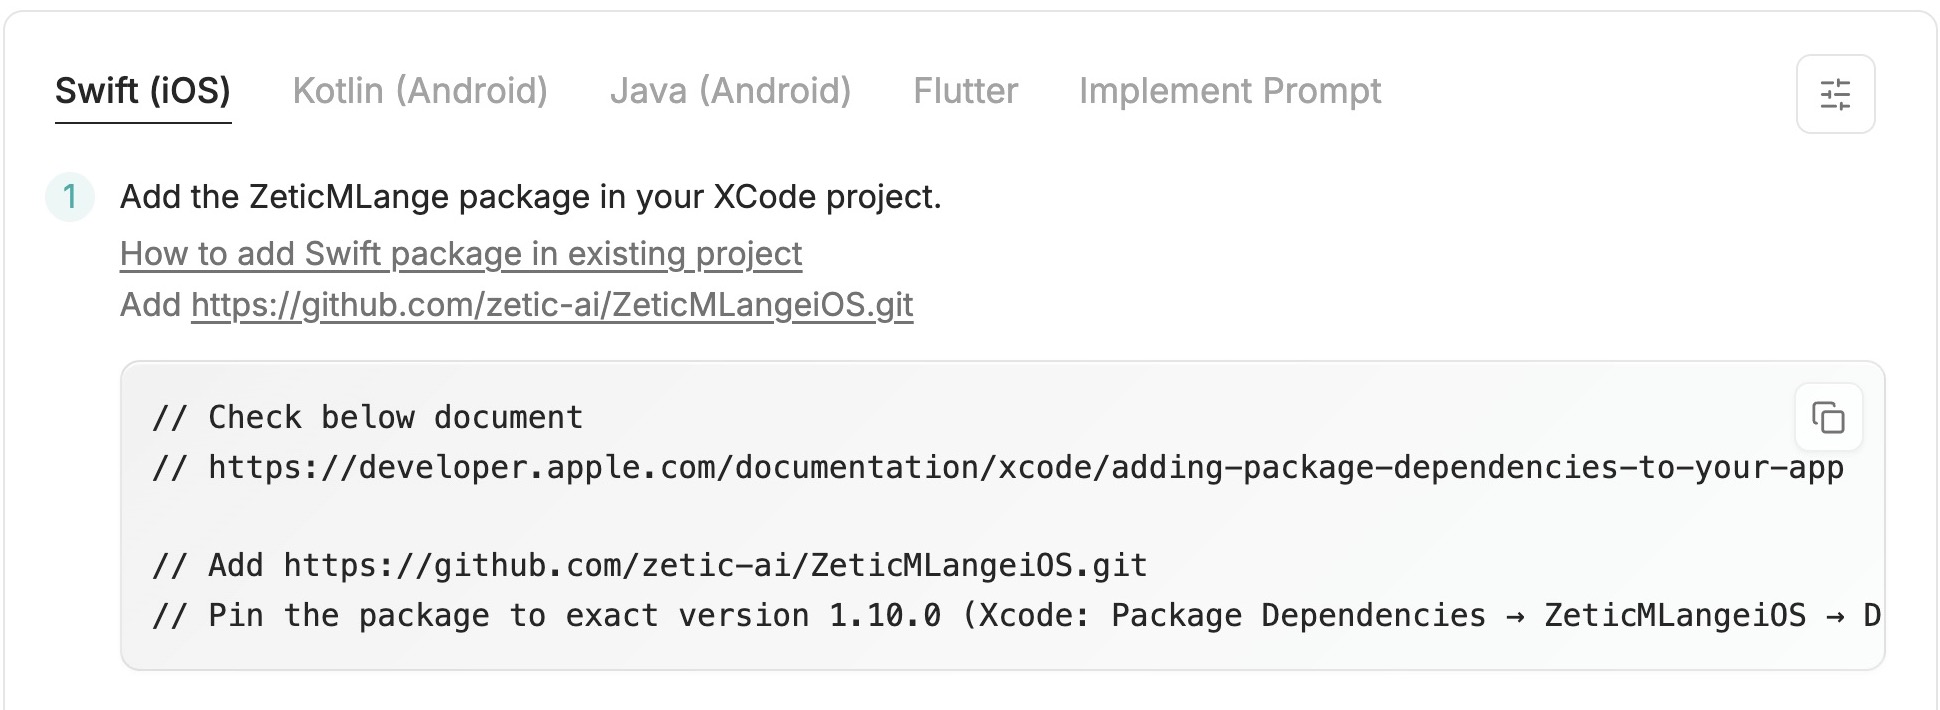
Copy the generated SDK code into your app and run your model on-device.
Core Capabilities
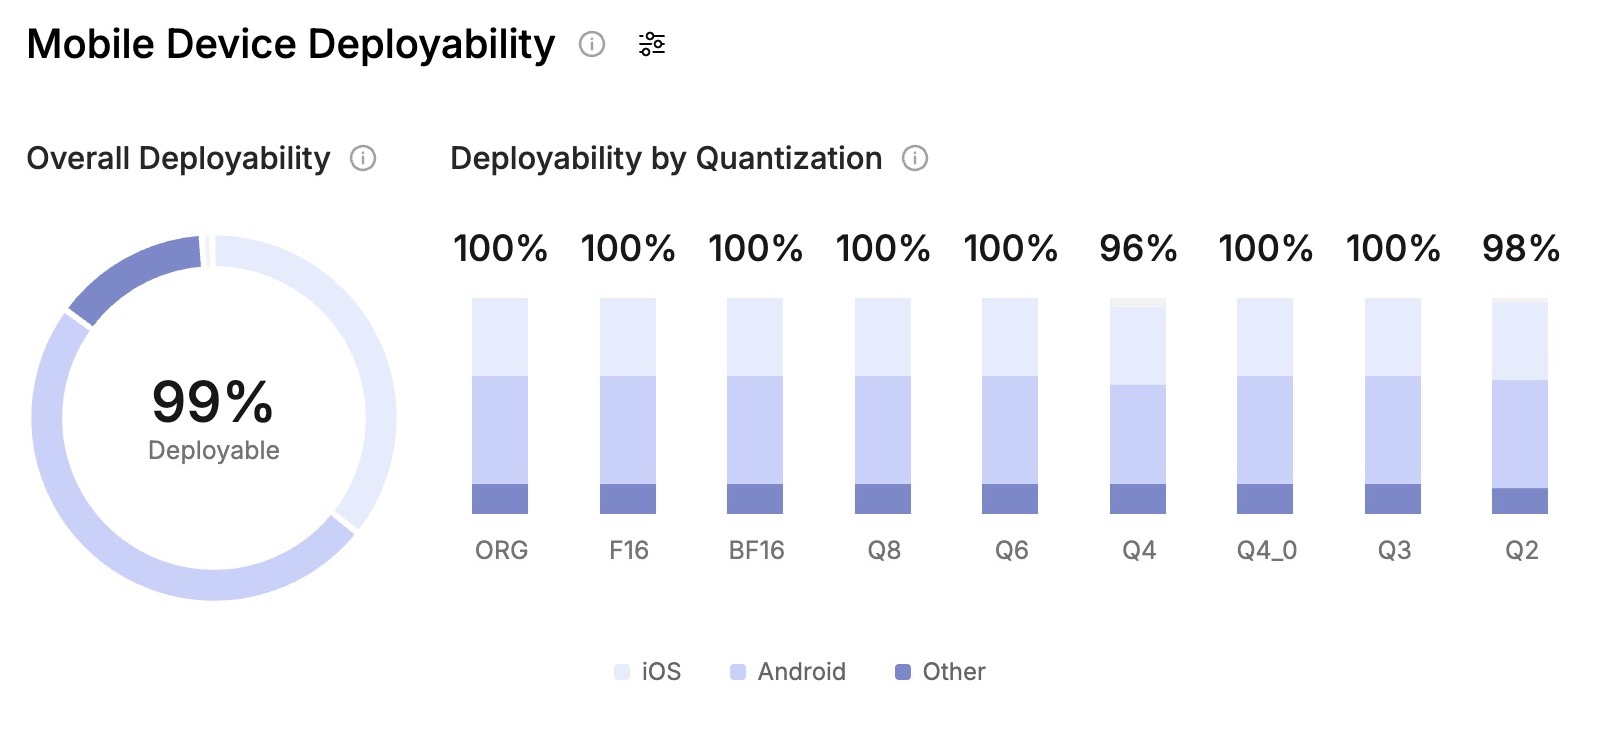
The SDK identifies the device and downloads the best-performing runtime, data type, and processor combination for your model.
Real accuracy and latency reports across 200+ physical devices.
CPU, GPU, and NPU hybrid support, handled automatically.
Model conversion, quantization, and optimization in one pipeline.
FAQ
Get answers to common questions here
No. We support TorchScript, TensorFlow and ONNX models directly. Our platform automatically handles conversion and quantization for on-device execution without needing your training data or altering weights
Open-source tools force you to manage fragmented pipelines: wrestling with CoreML for iOS, TFLite/LiteRT for Android, and endless hardware variations across devices. Melange unifies this into a single, streamlined workflow. We replace months of manual engineering with automated, deep NPU optimization that generic tools miss, and solve hardware fragmentation by providing real-world benchmarking across 200+ physical devices.
The savings are substantial because on-device AI decouples your user growth from your server costs. With cloud GPUs, doubling your users means doubling your infrastructure bill. By shifting computation to the user's device, your ongoing inference cost per new user drops to near zero. You stop paying indefinite cloud rent and shift to a highly scalable, predictable cost model.
Often, yes, because it eliminates network latency. While cloud GPUs have more raw power, the round-trip data transfer slows them down. On-device NPU execution is instantaneous, providing a smoother experience regardless of internet connection.
Your app will still work. Our runtime engine automatically detects available hardware. It prioritizes the NPU for speed, but seamlessly falls back to the GPU or CPU on older devices to guarantee broad compatibility.
With Google AI Edge, you can upload a model, optimize it, and see benchmarks, but taking it to a shipped app means building the deployment yourself. Melange does it all in one platform: upload, optimize, benchmark on real devices, and deploy a production-ready SDK to iOS or Android, in minutes. One workflow, model to shipped app.
Get started
Start free on mobile. Scale to enterprise when you need more.
Upload your model or explore the library. Start with the dashboard or CLI.
Try MelangeMelange Enterprise
Custom DevTools help enterprise teams adapt on-device AI deployment to their own hardware, runtime, and product requirements.
Talk to our team